Pyspark Remove Duplicates From Array Pyspark Remove Spaces From Column Values Aboutdataai au How To Remove Duplicates From Array Java DataTrained VBA To Remove Duplicates From Array Excel Pandas Drop Duplicates Explained Sharp Sight Remove Duplicates From Array In C QA With Experts 1 Answer Sorted by 0 dropDuplicates is the way to remove duplicates and yes this is slow So a better way is to not create duplicates in the first place Perhaps you can limit the duplicates by first calling array distinct before exploding This is all highly dependent on your input data
From pyspark sql import Window import pyspark sql functions as F Create a window of each group ordered by Date and containing all elements in a specified column h Window partitionBy SID orderBy Date rowsBetween Window unboundedPreceding Window unboundedFollowing Create a column in which you broadcast first Attribute value It is useful for removing duplicate records in a DataFrame The syntax for using distinct is as follows distinct cols where cols Optional The name s of the column s to use to
Remove Duplicates From Array In C QA With Experts 6 Different Methods JavaScript Remove Duplicates From Array Remove Duplicates From Unsorted Array 3 Approaches How To Remove Duplicates From Array Java DataTrained Data Trained Blogs JavaScript Remove Duplicates From An Array ParallelCodes Remove Duplicates From An Array JavaScriptSource Four Ways To Remove Duplicates From An Array In Kotlin How To Remove Duplicate Records From A Dataframe Using PySpark How To Remove Duplicates From A JavaScript Array
Pyspark Remove Duplicates From Array
 Pyspark Remove Duplicates From Array
https://aboutdataai219412358.files.wordpress.com/2021/07/image-47.png?w=1024
Method 1 Using distinct method It will remove the duplicate rows in the dataframe Syntax dataframe distinct Where dataframe is the dataframe name created from the nested lists using pyspark Example 1 Python program to drop duplicate data using distinct function Python3 print distinct data after dropping duplicate rows
Templates are pre-designed files or files that can be used for different purposes. They can save time and effort by providing a ready-made format and layout for producing different kinds of material. Templates can be utilized for personal or expert projects, such as resumes, invitations, flyers, newsletters, reports, presentations, and more.
Pyspark Remove Duplicates From Array

Javascript Remove Duplicates From Array With Examples

6 Different Methods JavaScript Remove Duplicates From Array
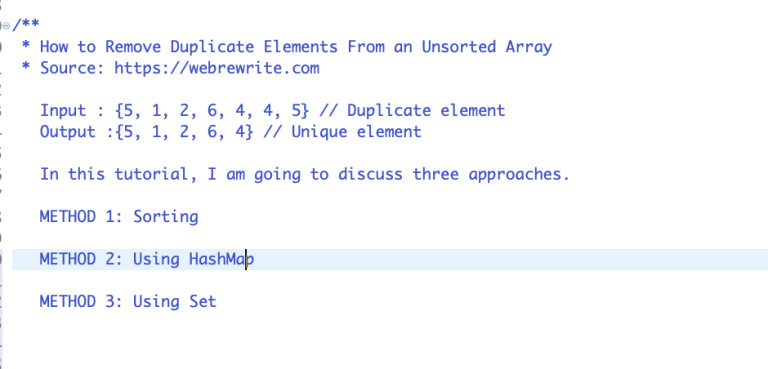
Remove Duplicates From Unsorted Array 3 Approaches
How To Remove Duplicates From Array Java DataTrained Data Trained Blogs
Remove Duplicates From An Array JavaScriptSource

Four Ways To Remove Duplicates From An Array In Kotlin

Collection function removes duplicate values from the array New in version 2 4 0 Parameters col Column or str name of column or expression Examples

The array distinct function in PySpark is a powerful tool that allows you to remove duplicate elements from an array column in a DataFrame It returns a new array column with distinct elements eliminating any duplicates present in the original array

Distinct and dropDuplicates in PySpark are used to remove duplicate rows but there is a subtle difference distinct considers all columns when identifying duplicates while dropDuplicates allowing you to specify a subset of columns to determine uniqueness Can distinct be used on specific columns only

One of the most straightforward methods to eliminate duplicate rows is using the distinct method which essentially returns a new DataFrame with unique rows Example in pyspark distinct df df distinct distinct df show

Return a new DataFrame with duplicate rows removed optionally only considering certain columns For a static batch DataFrame it just drops duplicate rows For a streaming DataFrame it will keep all data across triggers as intermediate state to drop duplicates rows
To handle duplicate values we may use a strategy in which we keep the first occurrence of the values and drop the rest dropduplicates Pyspark dataframe provides dropduplicates function that is used to drop duplicate occurrences of data inside a dataframe Syntax dataframe name dropDuplicates Column name In this Spark article you have learned how to remove DataFrame rows that are exact duplicates using distinct and learned how to remove duplicate rows based on multiple columns using dropDuplicate function with Scala example Related Articles Spark SQL Add row number to DataFrame Spark SQL Left Outer Join with Example
There are three common ways to drop duplicate rows from a PySpark DataFrame Method 1 Drop Rows with Duplicate Values Across All Columns drop rows that have duplicate values across all columns df new df dropDuplicates Method 2 Drop Rows with Duplicate Values Across Specific Columns