Spark Etl Example Run A Spark SQL based ETL Pipeline With Amazon EMR On Amazon EKS AWS Scala And Apache Spark In Tandem As A Next Generation ETL Framework GitHub R0NGSH3N simple spark etl Using Spark As ETL Tool To Show How Spark Data Lineage What Is Spark ETL Snowflake Web Jan 13 2023 nbsp 0183 32 Here s an example of how to use PySpark to read a CSV file clean and normalize the data and then write it to a new CSV file from pyspark sql import SparkSession Create a SparkSession spark
Web Apr 24 2019 nbsp 0183 32 Example of ETL Application Using Apache Spark and Hive In this article we ll read a sample data set with Spark on HDFS Hadoop File System do a simple analytical operation then write Web Aug 24 2021 nbsp 0183 32 Run a Spark SQL based ETL pipeline with Amazon EMR on Amazon EKS by Melody Yang Shiva Achari Daniel Maldonado and Igor Izotov on 24 AUG 2021 in Advanced 300 Amazon Elastic Kubernetes Service Amazon EMR Amazon EMR on EKS Analytics Compute Permalink Comments Share This blog post has been translated
What Is Spark ETL Snowflake Spark NORM CLOTHING Criar Pipelines DE ETL Com O Azure Databricks Azure Architecture Transition From Traditional ETL Tool To Apache Spark For ETL Application B Build A SQL based ETL Pipeline With Apache Spark On Amazon EKS Privacy Policy Spark Project Build A Real time ETL Pipeline For An IoT System Krasamo Develop Etl Pipeline Using Azure Data Factory And Databricks Lupon gov ph Home2 Spark MEDIA
Spark Etl Example
 Spark Etl Example
https://d2908q01vomqb2.cloudfront.net/b6692ea5df920cad691c20319a6fffd7a4a766b8/2021/06/28/bdb1267-image1.png
Web Oct 2 2022 nbsp 0183 32 We set the application name to Example Master node URL to local and set the location of the Jar files We are ready to create a Spark context We utilize the SparkContext object and call the getOrCreate function To this function we supply the configuration We call the SparkSession and provide it the Spark Context
Templates are pre-designed documents or files that can be utilized for numerous purposes. They can conserve effort and time by providing a ready-made format and layout for creating different sort of content. Templates can be used for personal or expert jobs, such as resumes, invitations, flyers, newsletters, reports, discussions, and more.
Spark Etl Example

Azure Data Factory ETL Azure Architecture Center
Spark NORM CLOTHING
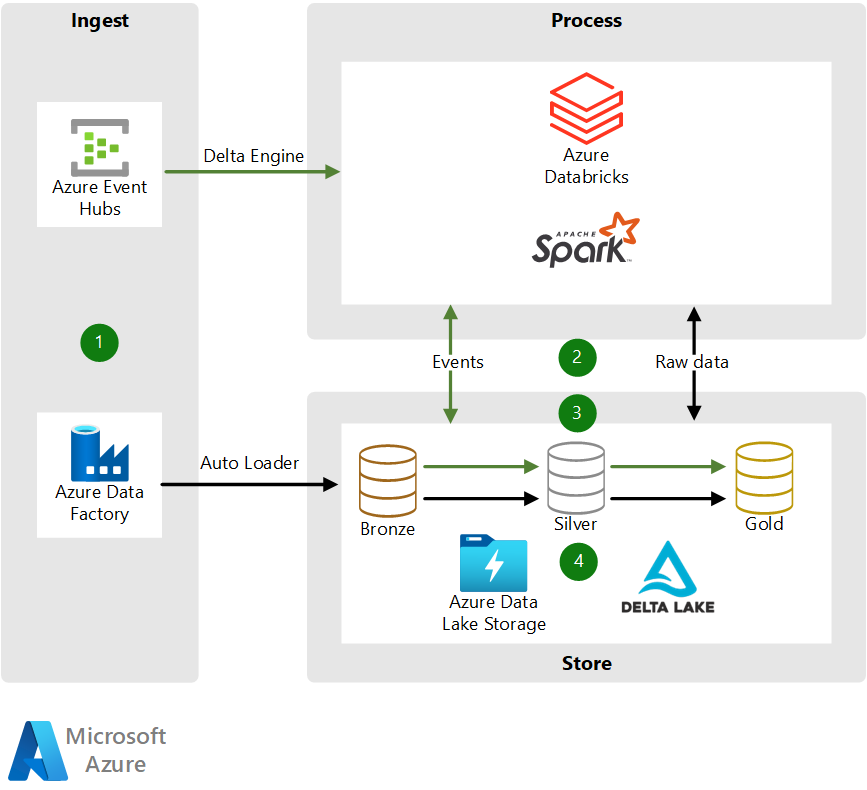
Criar Pipelines DE ETL Com O Azure Databricks Azure Architecture

Transition From Traditional ETL Tool To Apache Spark For ETL Application

Privacy Policy Spark Project
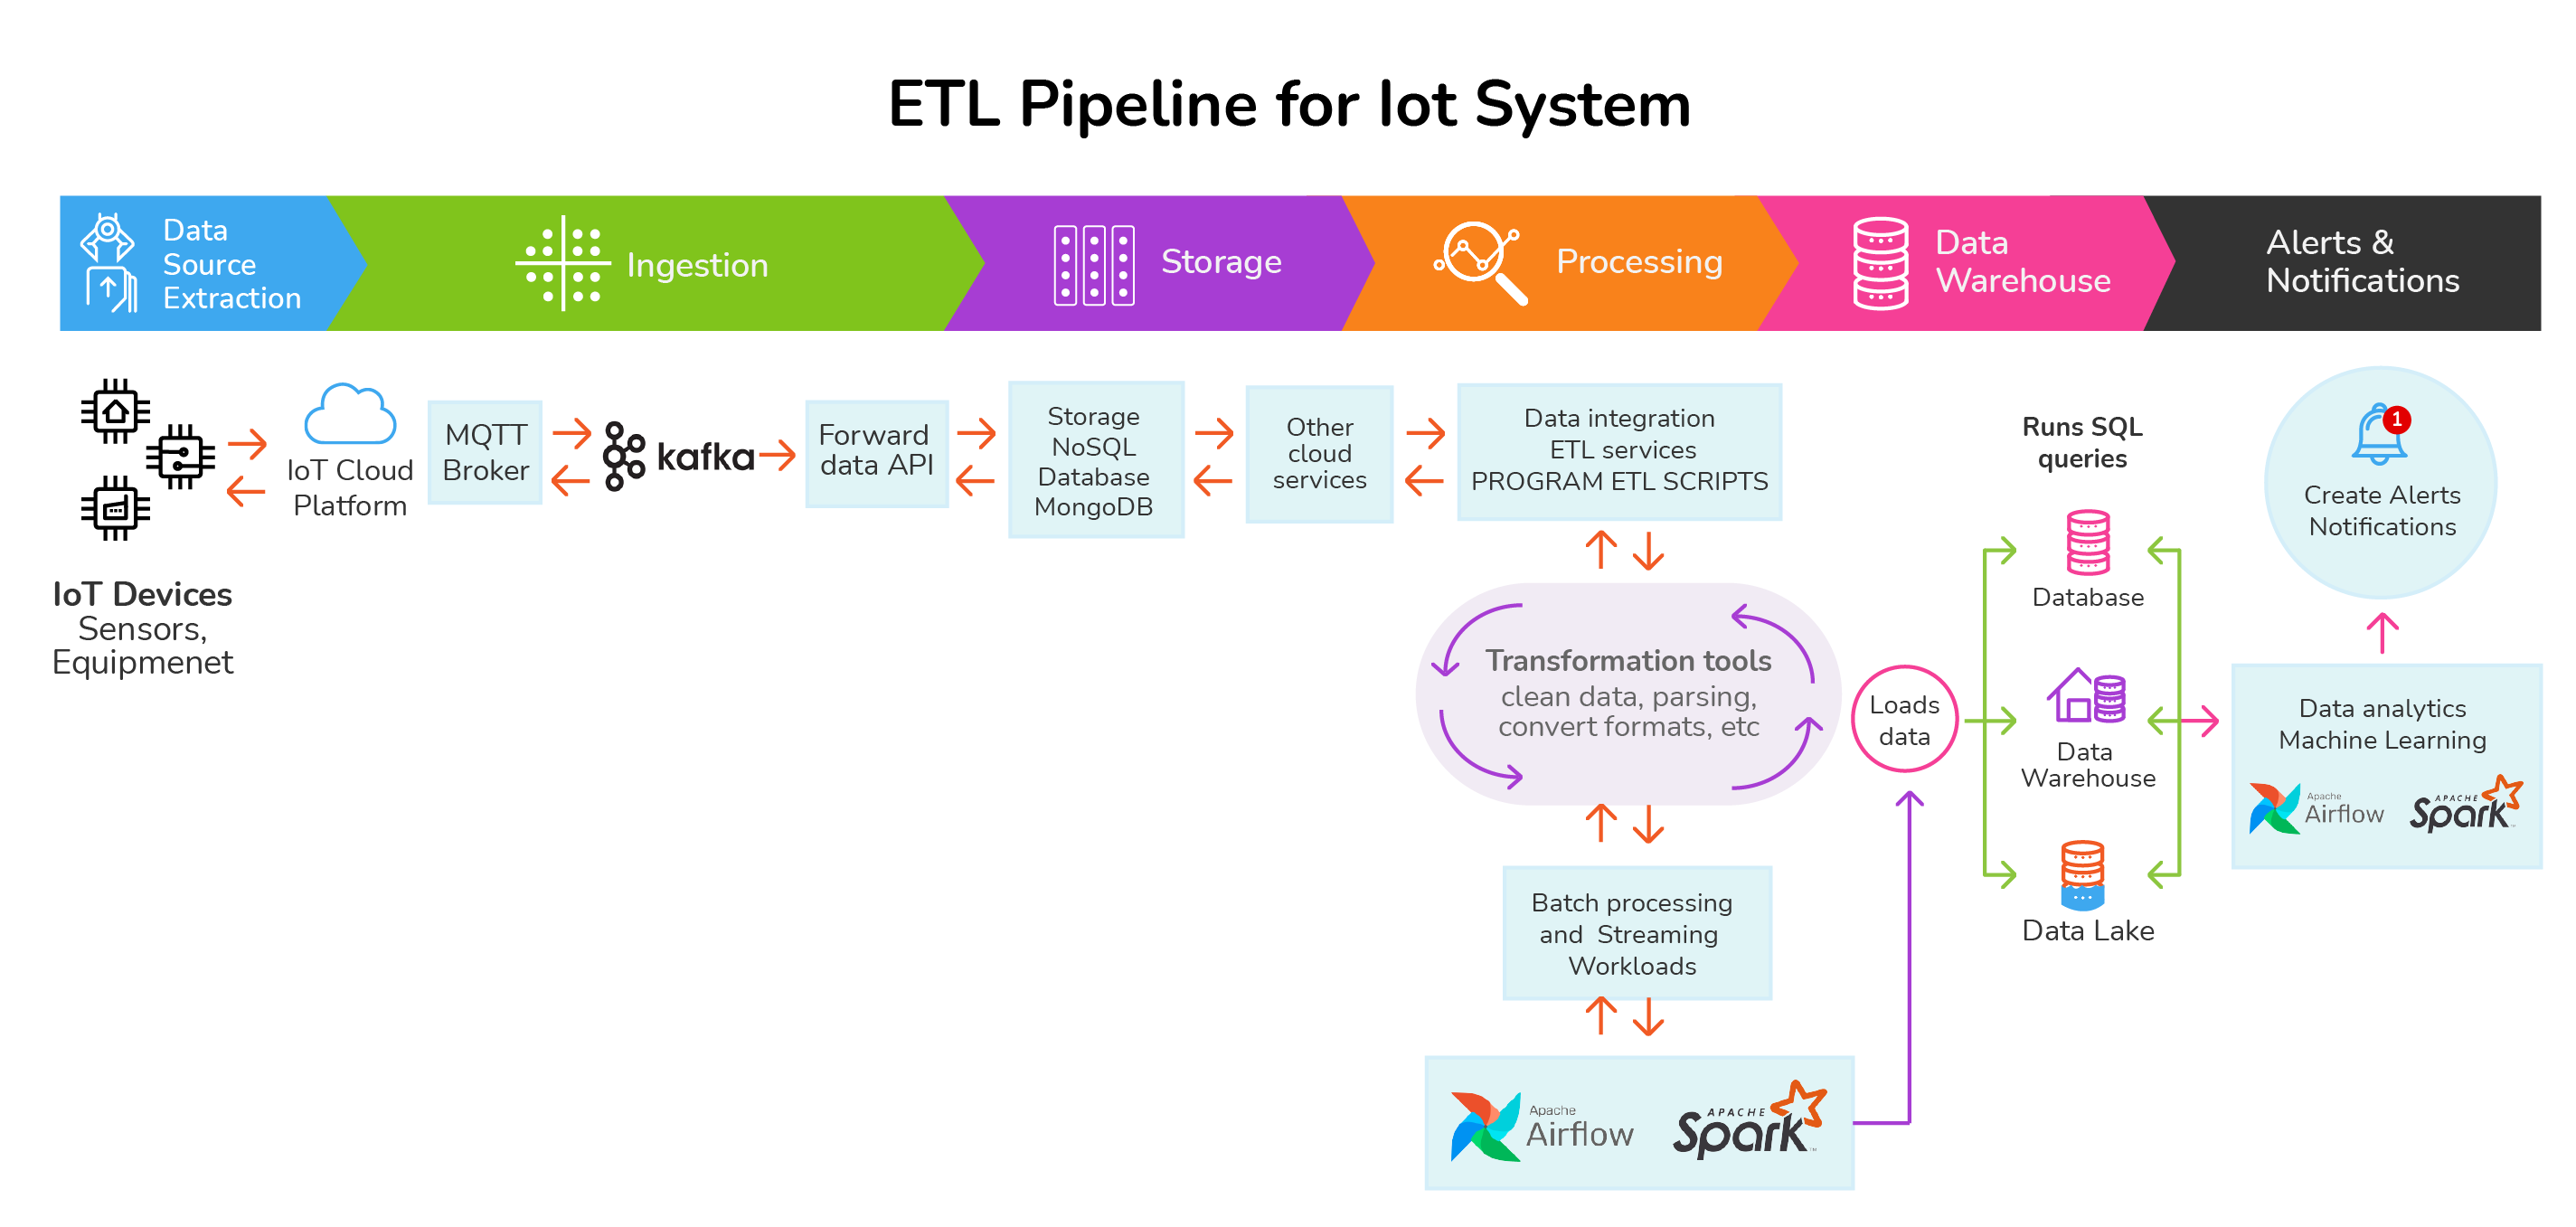
Build A Real time ETL Pipeline For An IoT System Krasamo

Web Nov 11 2019 nbsp 0183 32 Spark ETL Pipeline Dataset description Since 2013 Open Payments is a federal program that collects information about the payments drug and device companies make to physicians and teaching

Web January 12 2023 9 mins read Instead of writing ETL for each table separately you can have a technique of doing it dynamically by using the database MySQL PostgreSQL SQL Server and Pyspark Follow some steps to write code for better understanding I am breaking it into steps
Web May 27 2020 nbsp 0183 32 This article demonstrates how Apache Spark can be writing powerful ETL jobs using PySpark PySpark helps you to create more scalable processing and analysis of big data

Web Aug 24 2021 nbsp 0183 32 Arc abstracts from Apache Spark and container technologies in order to foster simplicity whilst maximizing efficiency Arc is used as a publicly available example to prove the ETL architecture It can be replaced by your own choice of in house build or other data framework that supports the declarative ETL build and deployment pattern

Web Oct 16 2020 nbsp 0183 32 This article explains 2 methods to set up Apache Spark ETL integration The first method that involves building a simple Apache Spark ETL is using Pyspark to load JSON data into a PostgreSQL Database The second method automates the ETL process using the Hevo Data Pipeline Read along to decide which method suits you the best
Web Jan 19 2017 nbsp 0183 32 We will show how easy it is to take an existing batch ETL job and subsequently productize it as a real time streaming pipeline using Structured Streaming in Databricks Using this pipeline we have converted 3 8 million JSON files containing 7 9 billion records into a Parquet table which allows us to do ad hoc queries on updated to Web Aug 6 2022 nbsp 0183 32 Python 3 6 with the libraries requests gt to download the files psycopg2 gt to connect to Postgres and execute SQL statements pyspark gt connect to Apache Spark Apache Spark installed in your local machine with the connection Jars from Postgres configured Docker and Docker Compose Used to create a Postgres and a Metabase BI
Web Demonstration of using Apache Spark to build robust ETL pipelines while taking advantage of open source general purpose cluster computing Topics python postgres vagrant spark etl example spark sql