Parquet File Format Documentation Parquet File Explained How To Resolve Parquet File Issue Understanding Big Data File Formats Vladsiv How To Read Parquet File In Pyspark Projectpro Efficient DataFrame Storage With Apache Parquet Blue Yonder Tech Blog WEB Apache Parquet is an open source column oriented data file format designed for efficient data storage and retrieval It provides efficient data compression and encoding schemes with enhanced performance to handle complex data in bulk Apache Parquet is designed to be a common interchange format for both batch and interactive workloads
WEB We have been concurrently developing the C implementation of Apache Parquet which includes a native multithreaded C adapter to and from in memory Arrow data PyArrow includes Python bindings to this code which thus enables reading and writing Parquet files with pandas as well WEB The Apache Parquet Website Documentation Download Apache Parquet is a columnar storage format available to any project in the Hadoop ecosystem regardless of the choice of data processing framework data model or programming language
Efficient DataFrame Storage With Apache Parquet Blue Yonder Tech Blog Parquet File Format Everything You Need To Know Data Mozart Sample Parquet File Download Btslineartdrawingsimplerm Parquet File Explained Parquet File Explained Beginners Guide To Columnar File Formats In Spark And Hadoop Sample Parquet File Download Earlyvanhalensongs Parquet File With Example CommandsTech Spark File Format Showdown CSV Vs JSON Vs Parquet Garren s Big
Parquet File Format Documentation
 Parquet File Format Documentation
https://static.wixstatic.com/media/c064dc_def5d80cccf2430693e3b9bc3c3ab414~mv2.png/v1/fill/w_1000,h_443,al_c,usm_0.66_1.00_0.01/c064dc_def5d80cccf2430693e3b9bc3c3ab414~mv2.png
WEB Apr 20 2023 nbsp 0183 32 Apache Parquet is a file format designed to support fast data processing for complex data with several notable characteristics 1 Columnar Unlike row based formats such as CSV or Avro Apache Parquet is column oriented meaning the values of each table column are stored next to each other rather than those of each record
Pre-crafted templates provide a time-saving solution for producing a diverse range of documents and files. These pre-designed formats and layouts can be utilized for numerous personal and professional jobs, consisting of resumes, invitations, leaflets, newsletters, reports, discussions, and more, enhancing the material development process.
Parquet File Format Documentation
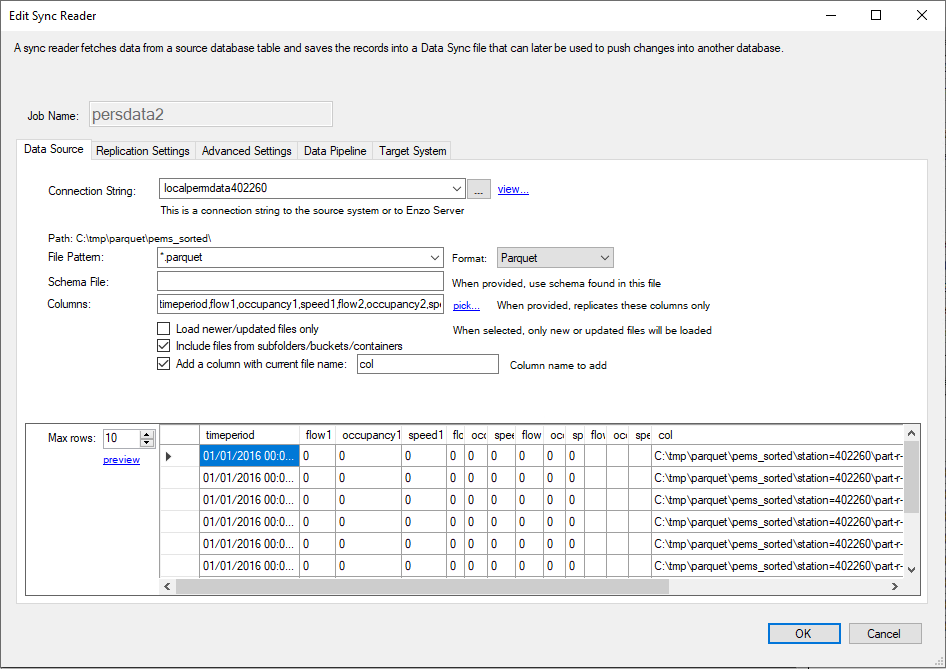
Enzo Unified Read Write Update Parquet Files With SQL Server And
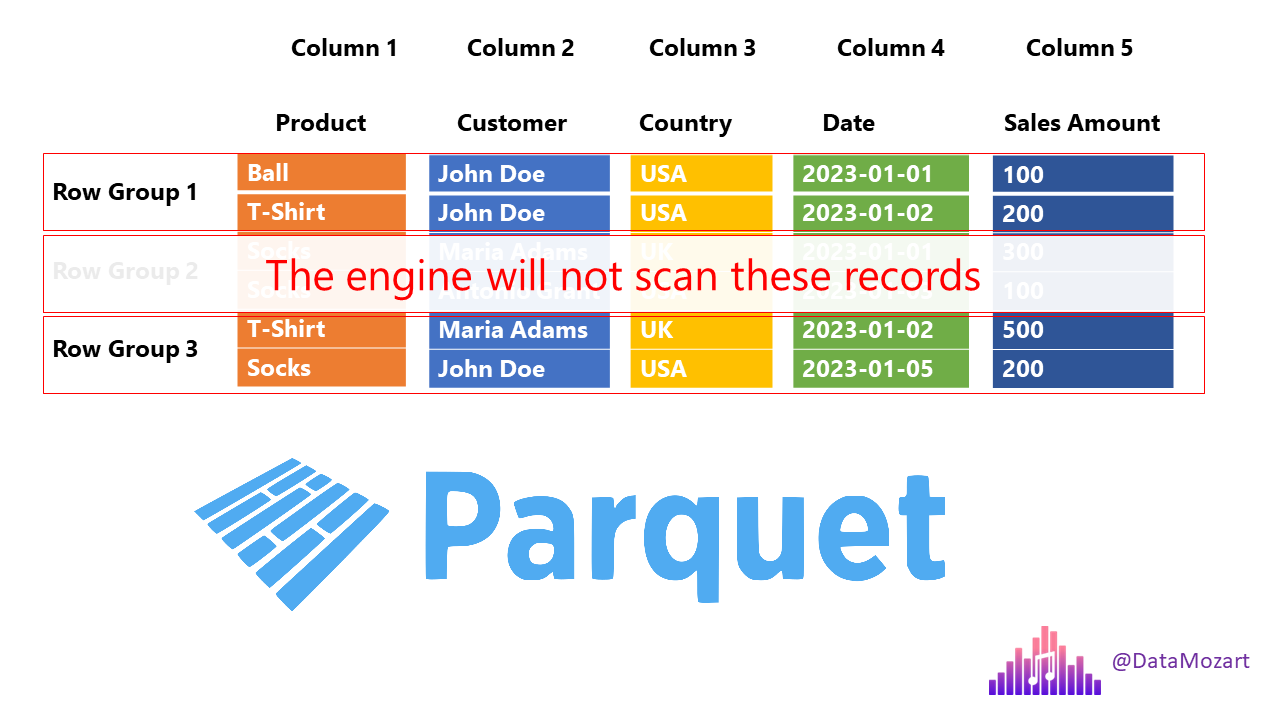
Parquet File Format Everything You Need To Know Data Mozart

Sample Parquet File Download Btslineartdrawingsimplerm

Parquet File Explained
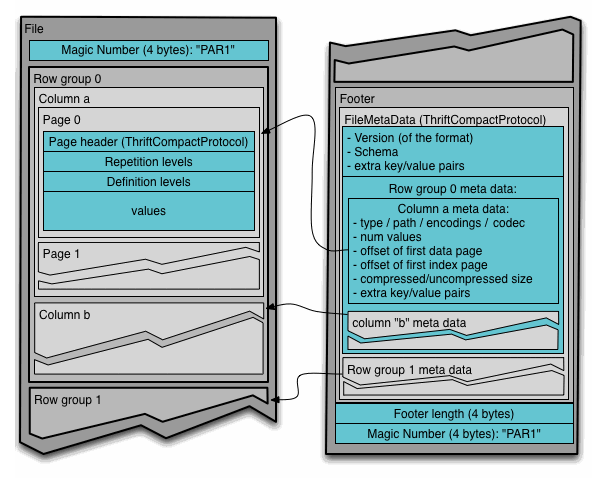
Beginners Guide To Columnar File Formats In Spark And Hadoop

Sample Parquet File Download Earlyvanhalensongs

WEB Jan 14 2024 nbsp 0183 32 Documentation about the Parquet File Format This file and the thrift definition should be read together to understand the format 4 byte magic number quot PAR1 quot lt Column 1 Chunk 1 Column Metadata gt lt Column 2 Chunk 1 Column Metadata gt

WEB Mar 24 2022 nbsp 0183 32 Apache Parquet is a columnar storage format available to any project in the Hadoop ecosystem regardless of the choice of data processing framework data model or programming language Motivation Last modified March 24 2022 Final Squash 3563721 Apache Parquet Privacy Policy All about Parquet

WEB Mar 24 2022 nbsp 0183 32 Welcome to the documentation for Apache Parquet Here you can find information about the Parquet File Format including specifications and developer resources Overview All about Parquet Concepts Glossary of relevant terminology File Format Documentation about the Parquet File Format Developer Guide

WEB Parquet is a columnar format that is supported by many other data processing systems Spark SQL provides support for both reading and writing Parquet files that automatically preserves the schema of the original data When reading Parquet files all columns are automatically converted to be nullable for compatibility reasons

WEB Parquet is a columnar format that is supported by many other data processing systems Spark SQL provides support for both reading and writing Parquet files that automatically preserves the schema of the original data When writing Parquet files all columns are automatically converted to be nullable for compatibility reasons
WEB Mar 24 2022 nbsp 0183 32 File Format Documentation about the Parquet File Format This file and the thrift definition should be read together to understand the format 4 byte magic number quot PAR1 quot lt Column 1 Chunk 1 Column Metadata gt lt Column 2 Chunk 1 Column Metadata gt lt Column N Chunk 1 Column Metadata gt lt Column 1 Chunk 2 Column Metadata gt WEB Follow this article when you want to parse the Parquet files or write the data into Parquet format Parquet format is supported for the following connectors Amazon S3 Amazon S3 Compatible Storage Azure Blob Azure Data Lake Storage Gen1 Azure Data Lake Storage Gen2 Azure Files File System FTP Google Cloud Storage HDFS HTTP Oracle
WEB Parquet is a columnar format that is supported by many other data processing systems Spark SQL provides support for both reading and writing Parquet files that automatically preserves the schema of the original data When reading Parquet files all columns are automatically converted to be nullable for compatibility reasons